

AI Orchestration & Governance Platform
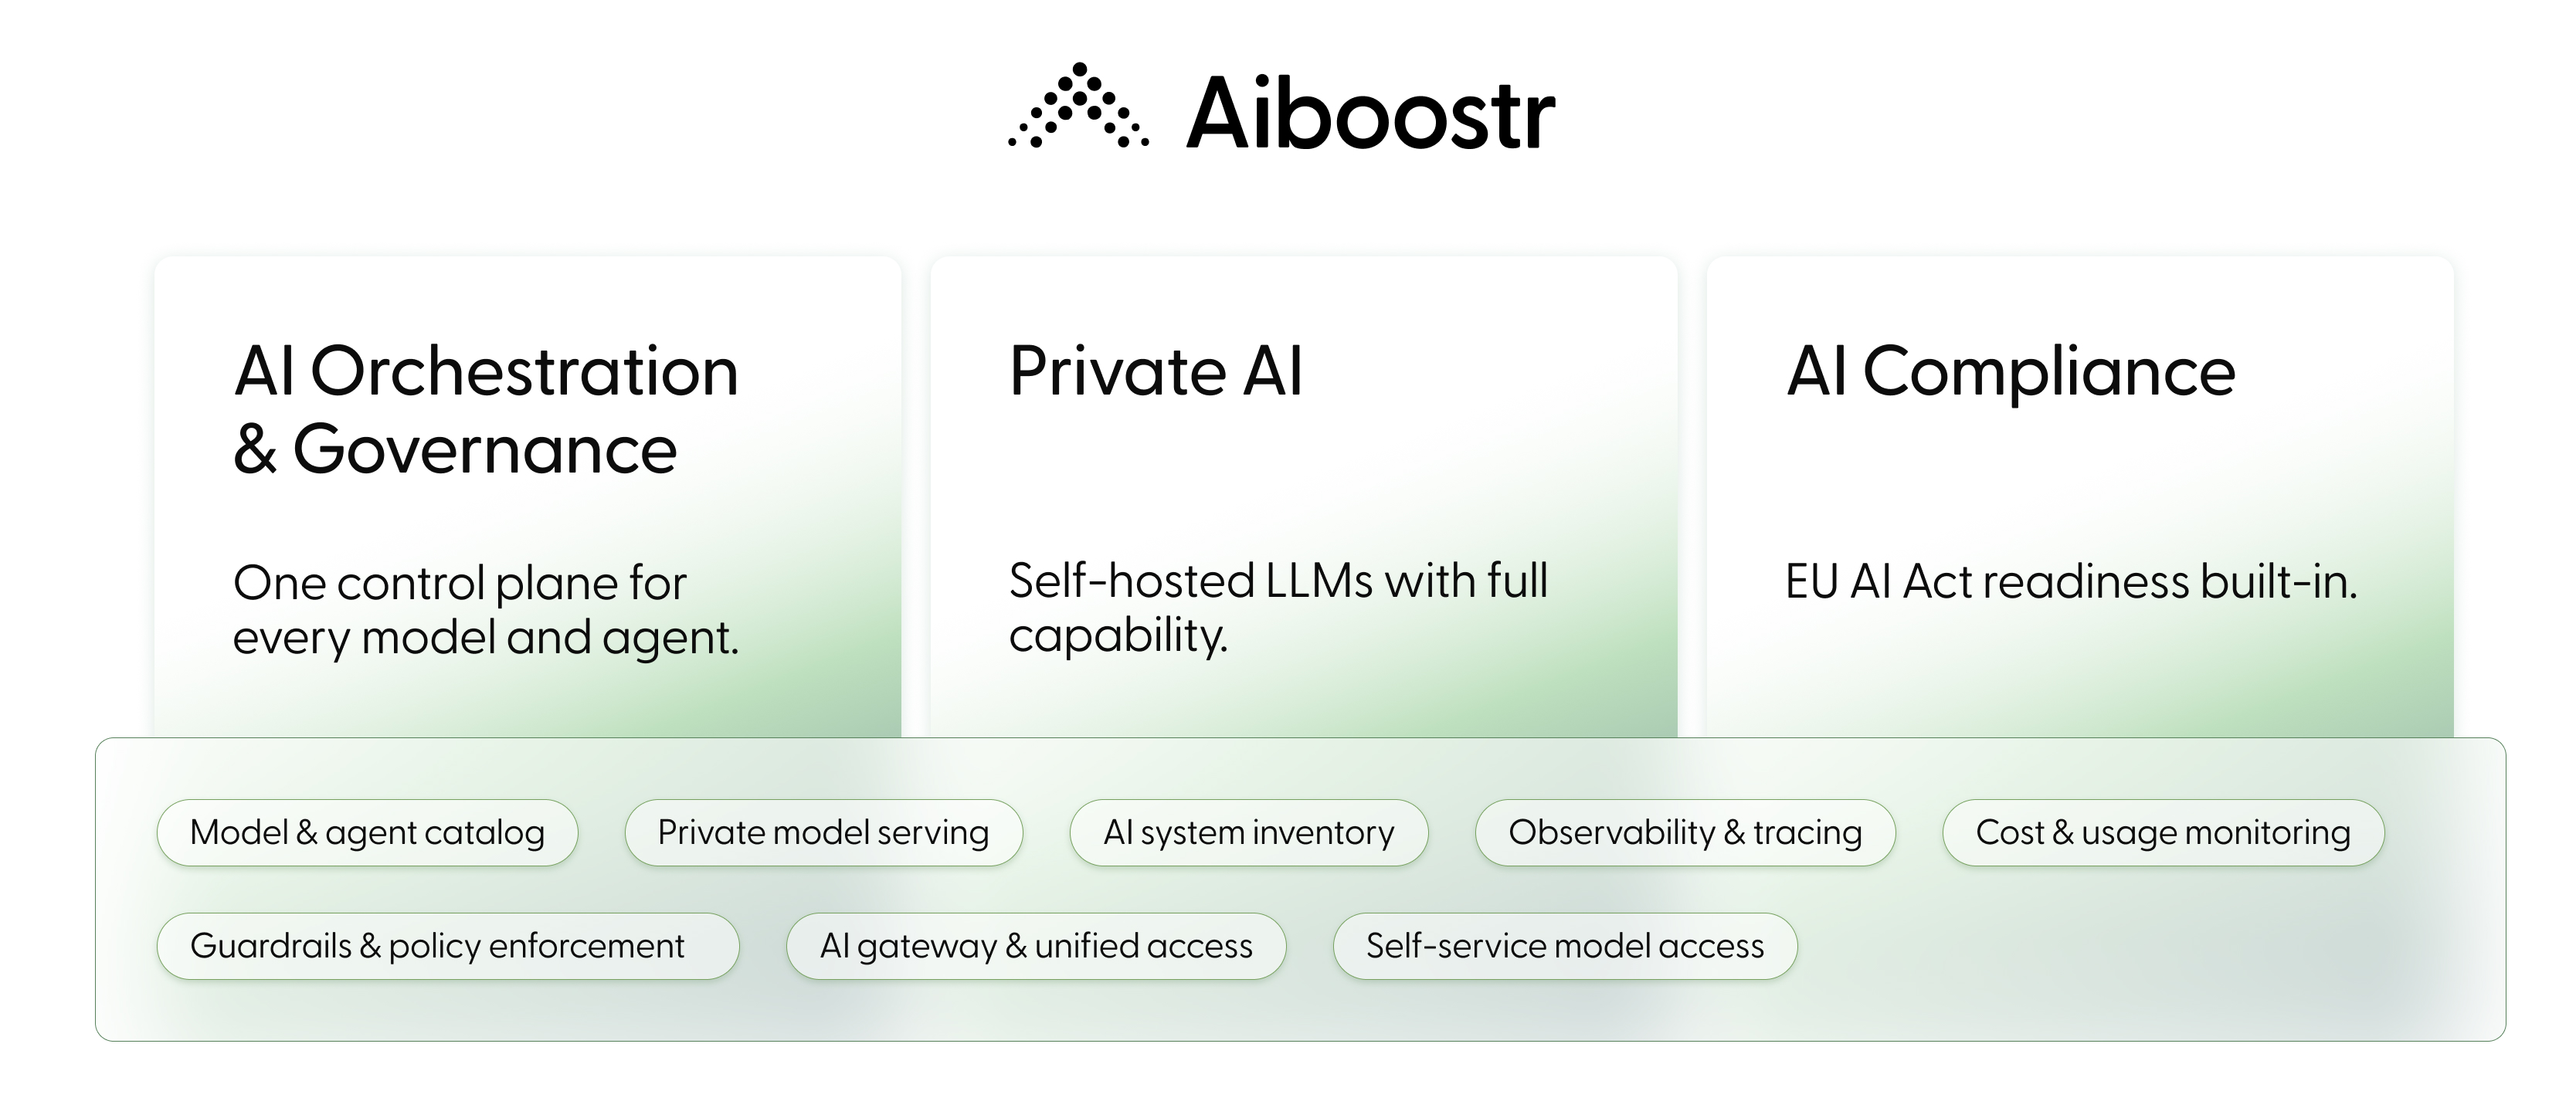
Aiboostr is the enterprise AI governance platform that gives companies full control over how AI agents and models are deployed, accessed, and governed across the organization.
Bring structure and AI governance to enterprise AI
End shadow AI - govern all AI usage from a single control plane
Manage access, cost, and security across every department and use case - with full visibility into which models are deployed, who uses them, and how data flows through the system.
Stay compliant with the EU AI Act regulation
Built-in governed AI system inventory, guardrails, and interaction logging address EU AI Act compliance requirements. Compliance embedded in the platform, not added as an afterthought.
Reduce operational overhead through self-service
A self-service catalog of models and agents lets business units discover, request, and access AI capabilities independently — without manual provisioning by platform teams for every new use case. Governance stays centralized; delivery stays self-service.

What is Aiboostr?
Watch how Aiboostr works in the three places enterprise teams reach for it first: orchestration, private AI, and EU AI Act evidence. One control plane for every model, agent, and prompt, running inside infrastructure you already own.



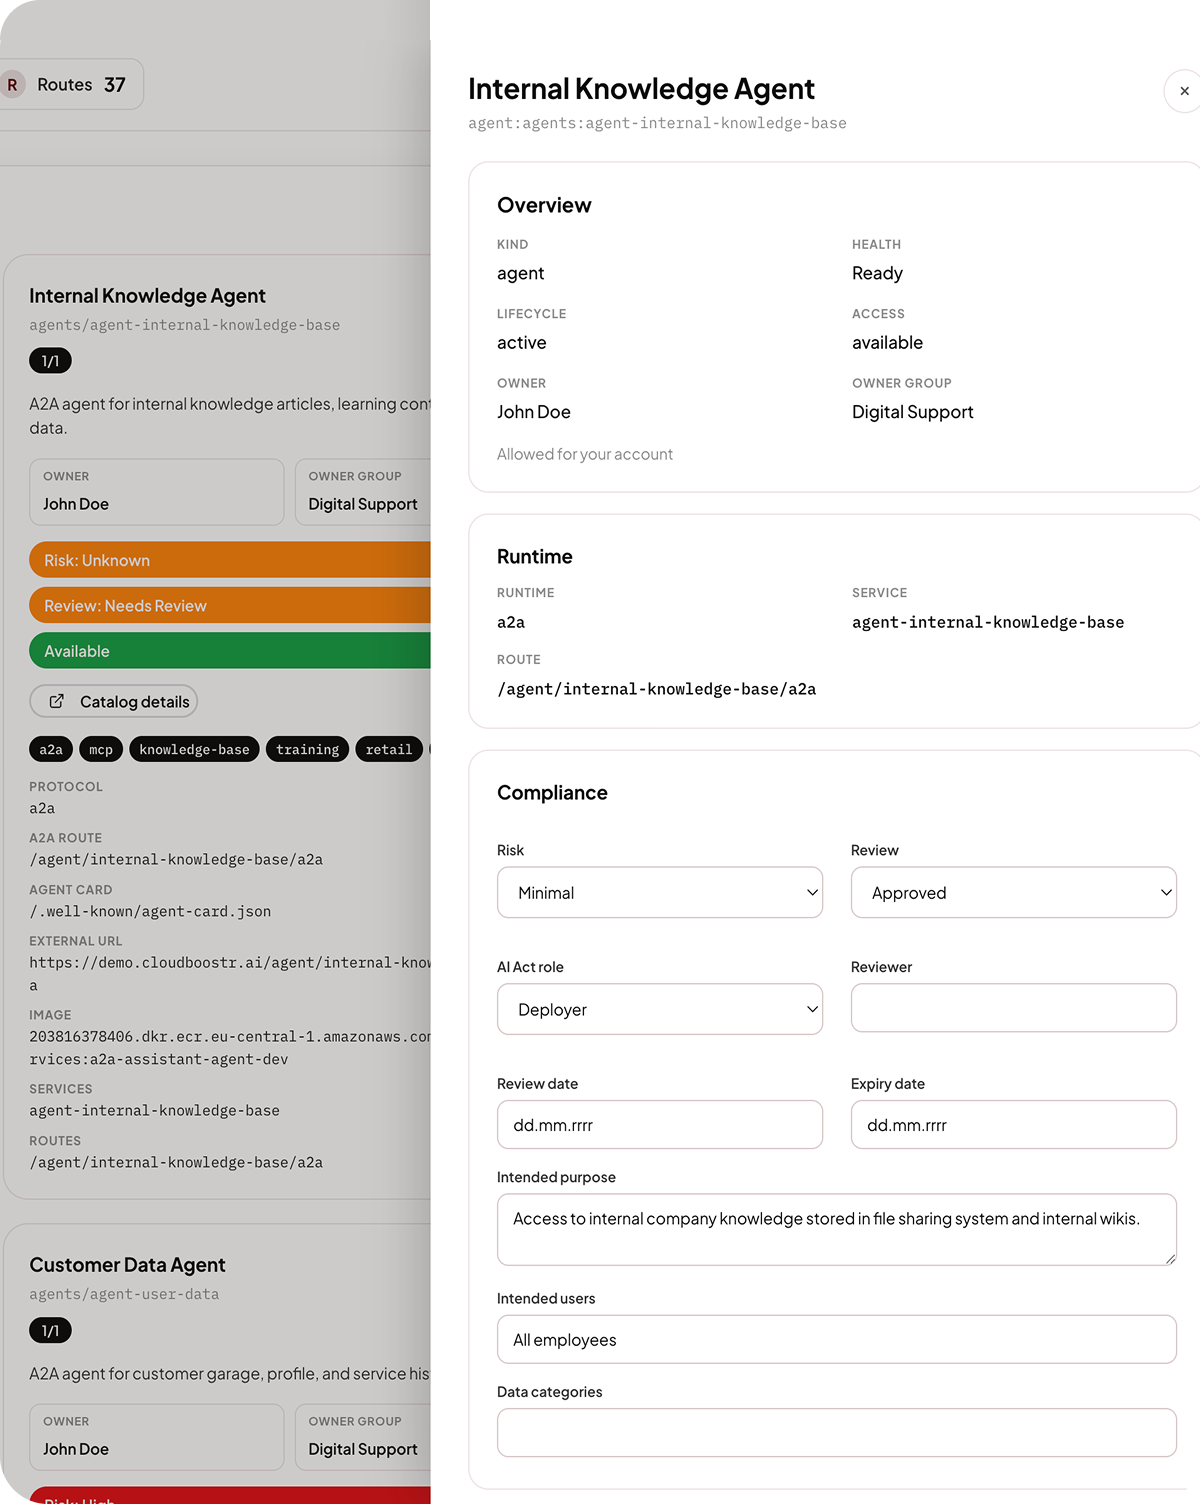
Governed AI, three ways to begin
Aiboostr for AI Orchestration
Every model, agent, and prompt under control.
As AI projects multiply across departments, visibility and control erode and shadow AI spreads. Aiboostr provides a unified control plane for all model access, cost governance, and agent governance - across every team and use case.

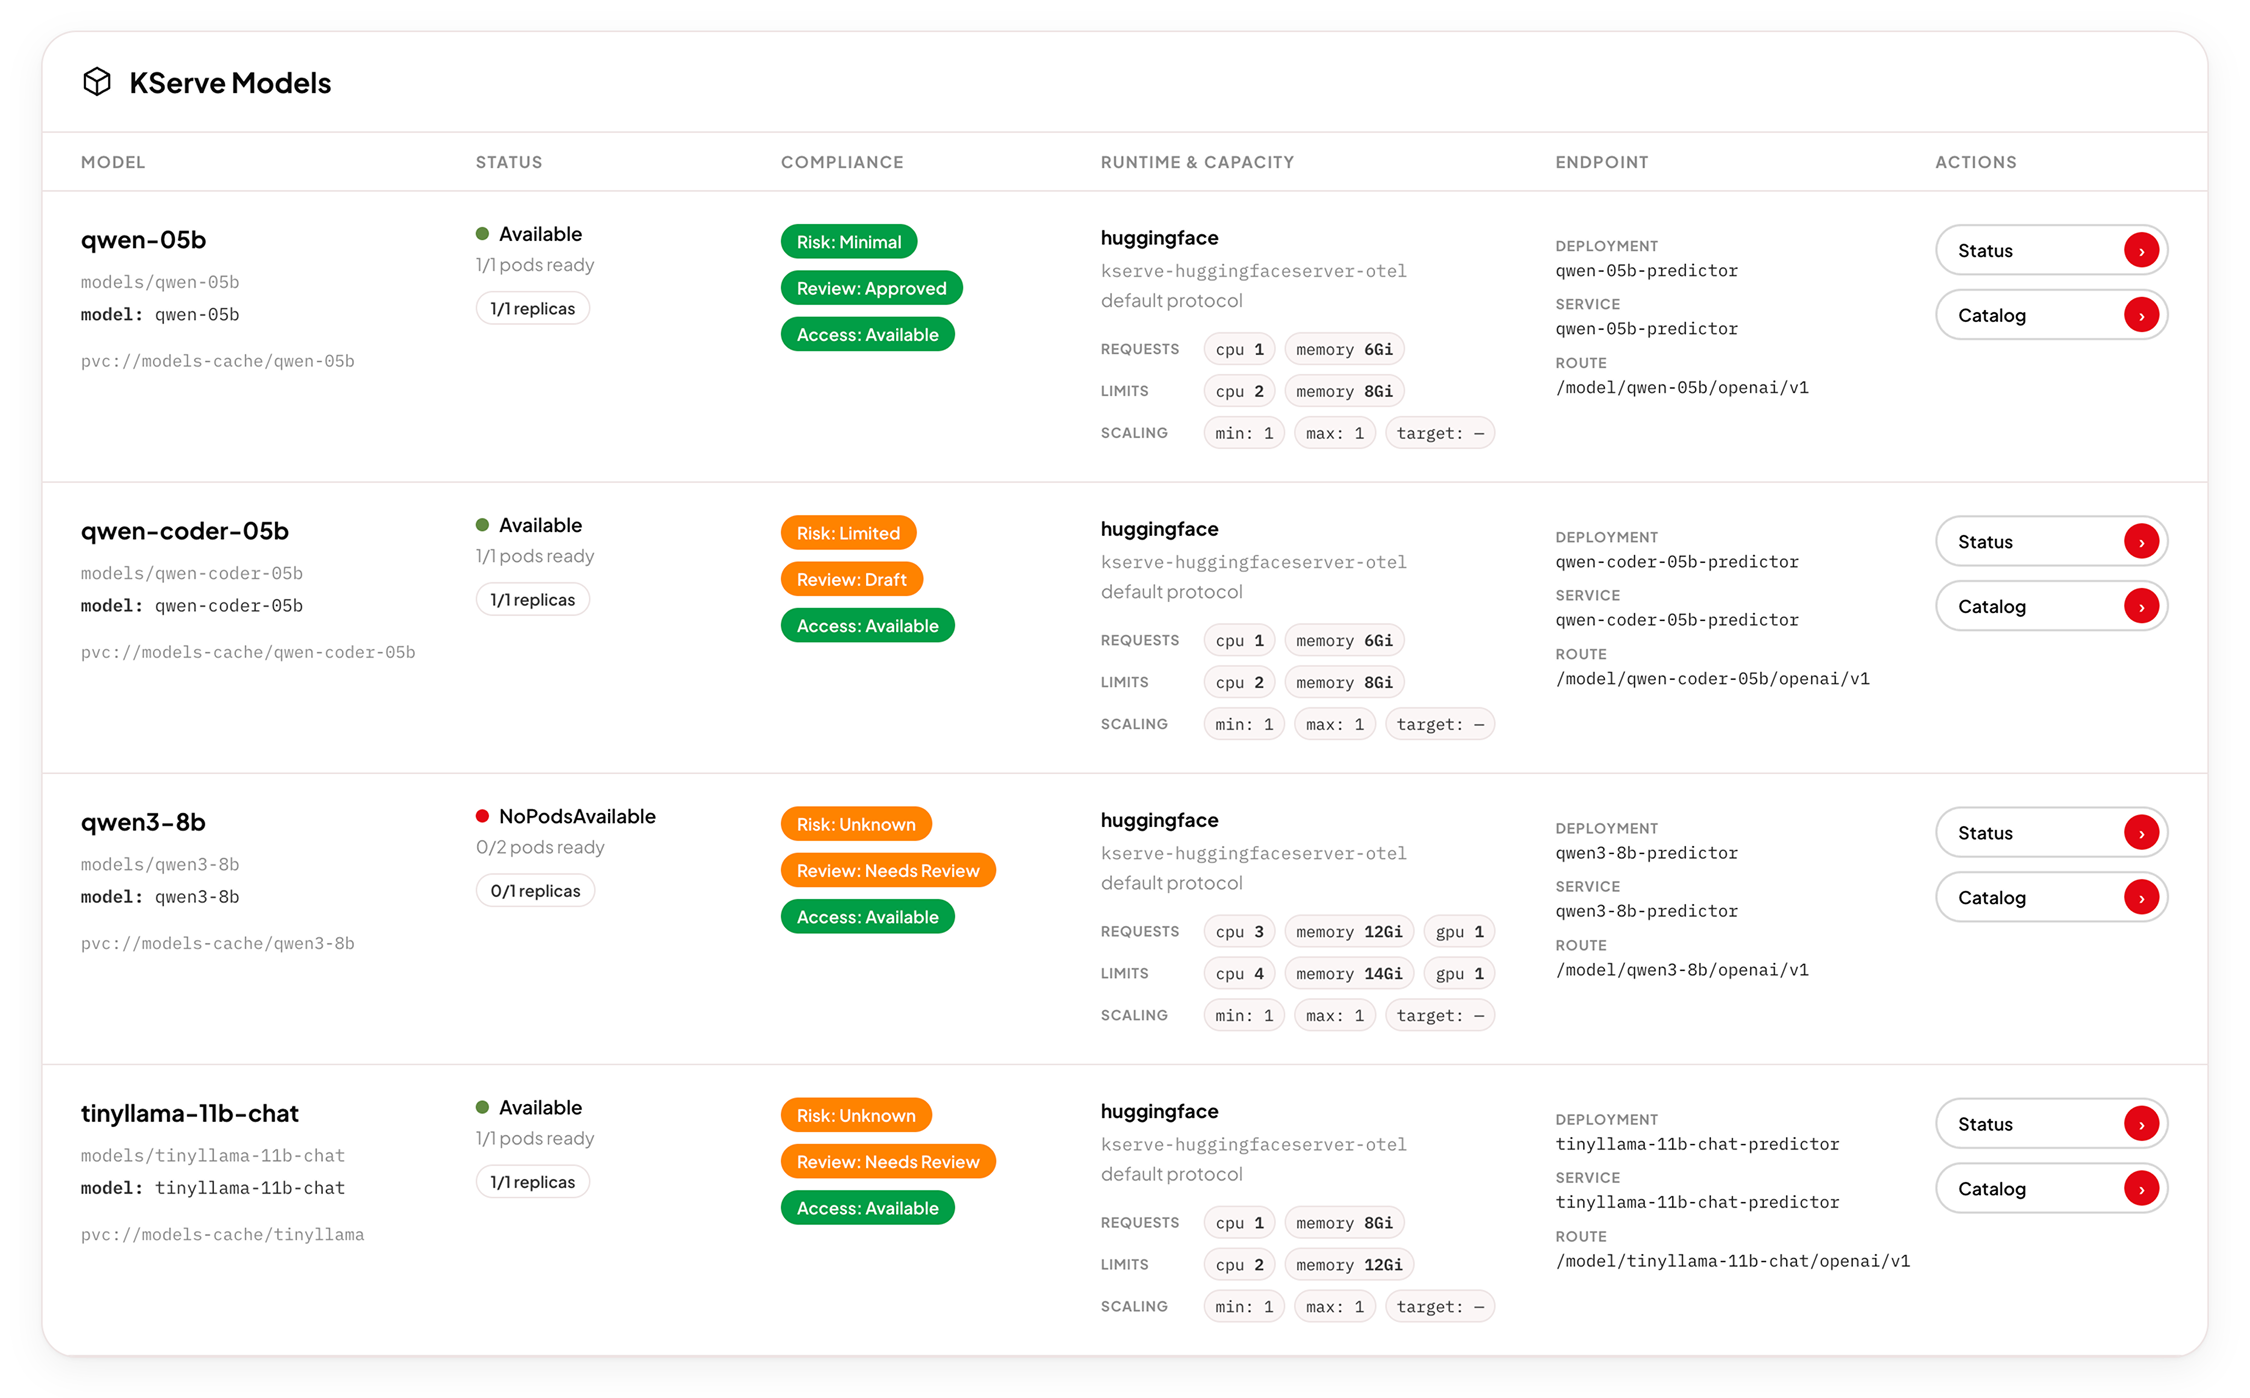
Aiboostr for Private AI
Private LLMs within your environment.
Routing sensitive data through external AI APIs creates regulatory and security risk. Aiboostr lets you run open-source LLMs directly on your own infrastructure — full AI capability, zero data exposure.
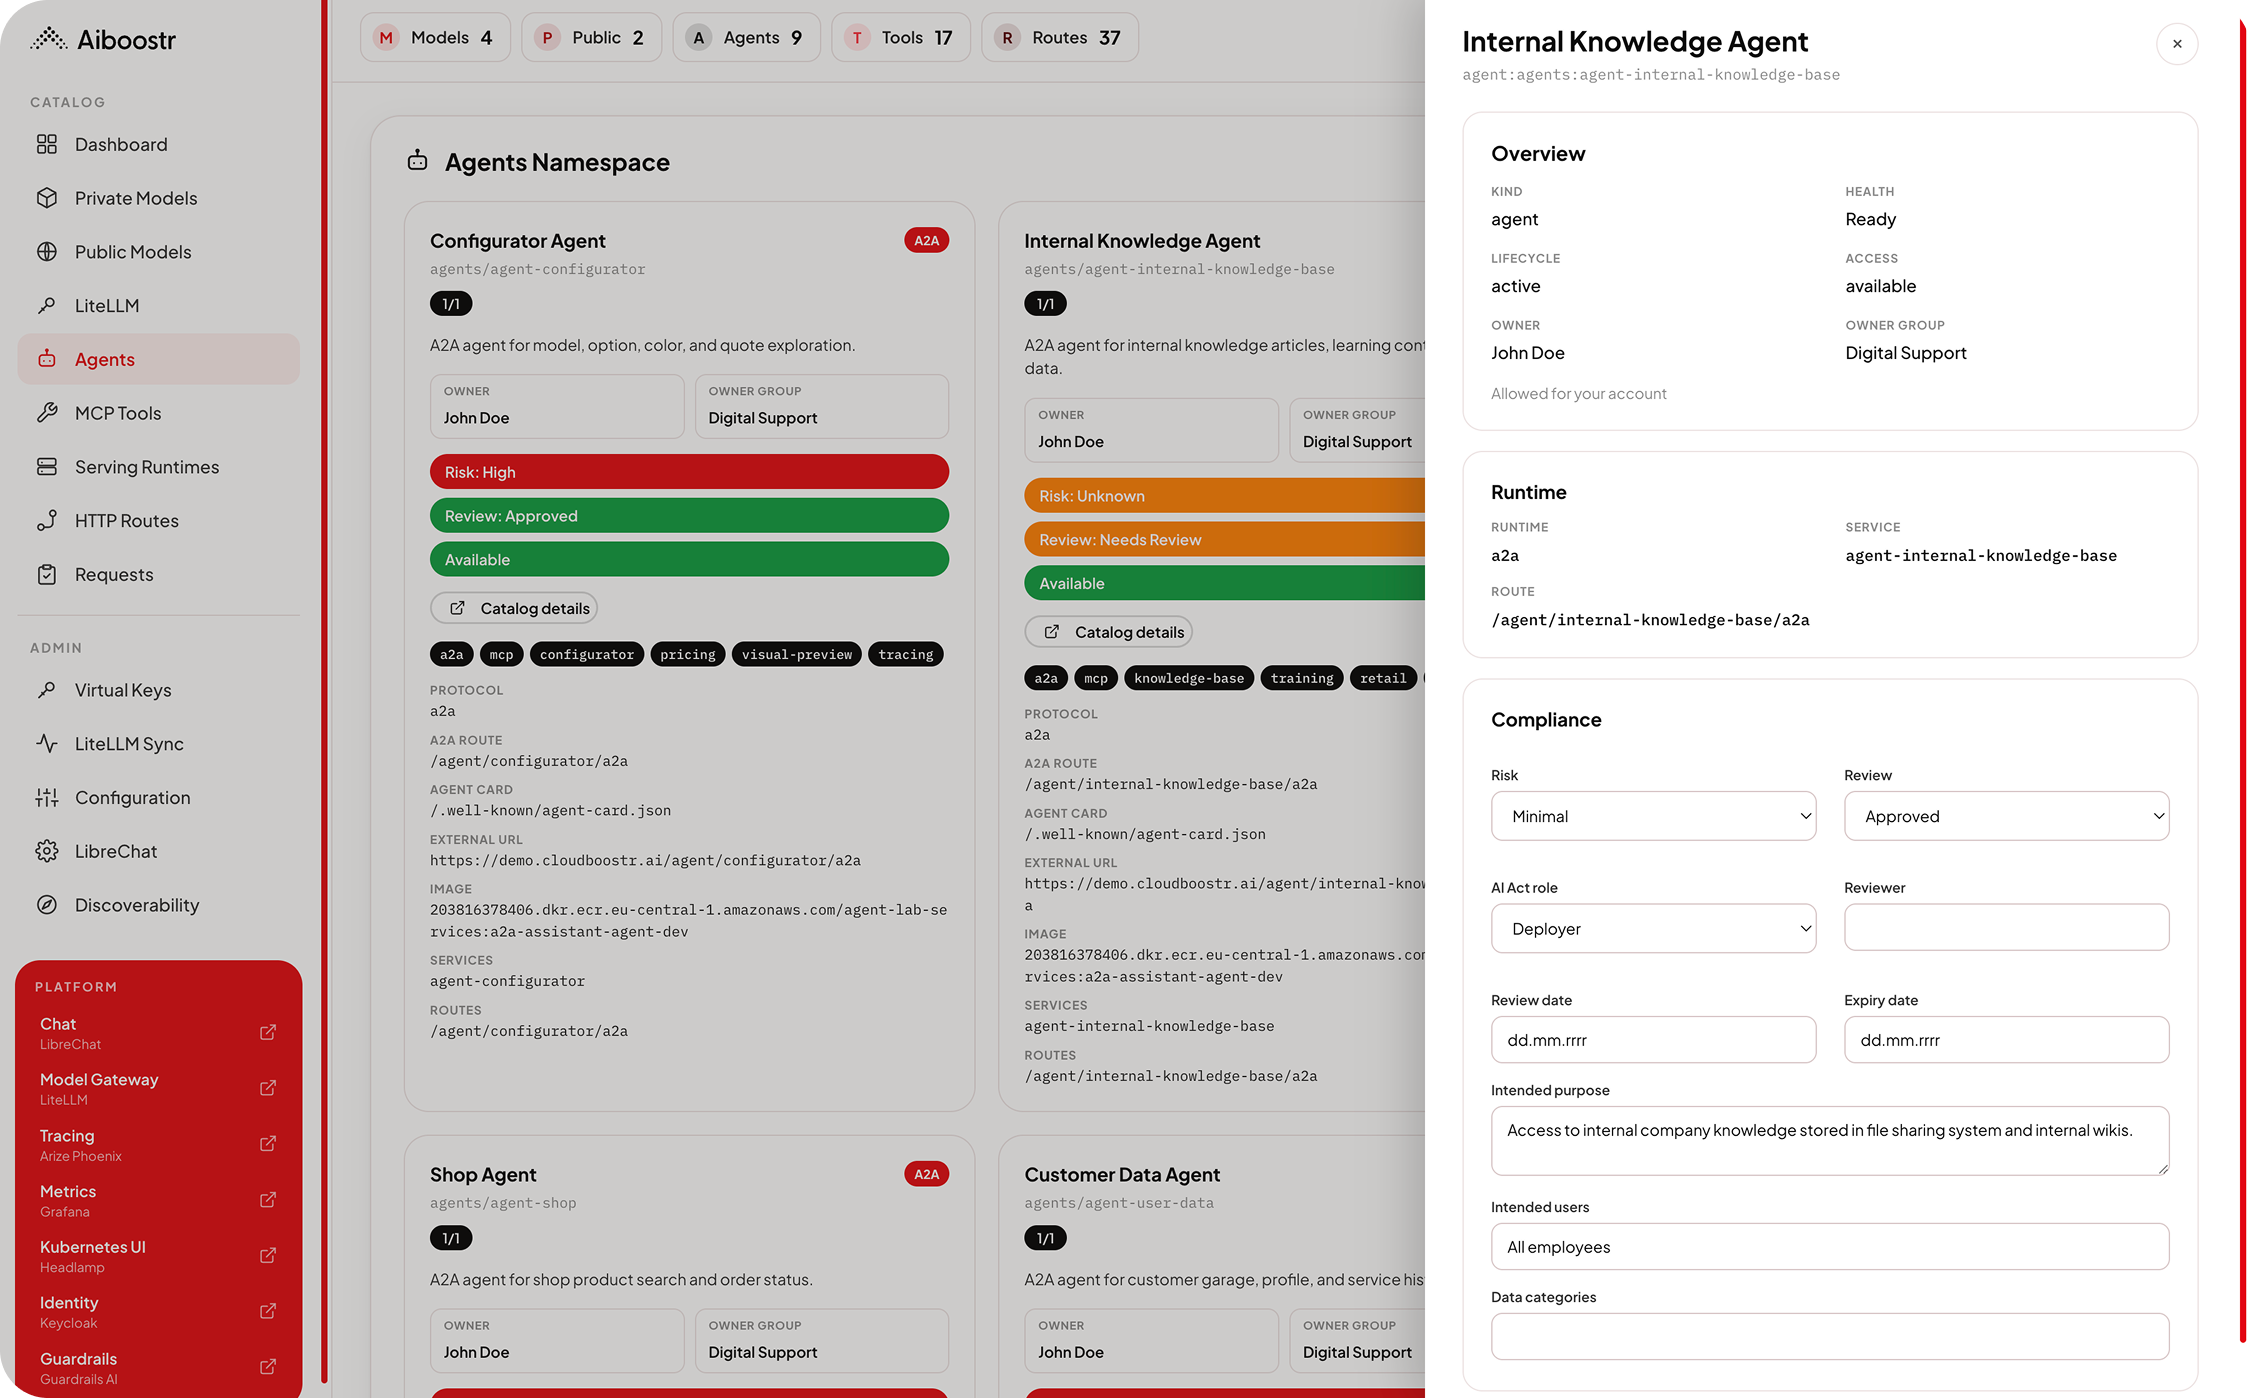
Aiboostr for EU AI Act
EU AI Act compliance built into your AI infrastructure.
The EU AI Act introduces operational obligations for organizations using AI systems. Aiboostr delivers the infrastructure to meet them — AI system inventory, policy enforcement, log retention, and continuous monitoring.
Everything you need to govern AI at enterprise scale
AI gateway and unified access
The AI gateway is a single access point for all models - private and public. Rate limiting, token budgets, per-team policies, and a full audit trail on every call.
Model and agent catalog
All AI models and agents registered in one discovery catalog. Teams find, request access to, and reuse existing capabilities without going through IT each time.
Private model serving
Optimized inference for self-hosted LLMs and predictive models - with autoscaling, model versioning, and staged deployments.
Agent runtime and MCP integration
Stateful execution environment for agentic AI and multi-agent workflows. MCP-based tool integration connects agents to enterprise systems and APIs through a governed interface.
Cost and usage monitoring
Track token consumption, API costs, and usage patterns across teams, projects, and models - with attribution for budget control.
Observability and tracing
Prompt and response level traces. Full execution tracing for agent runs — every LLM call, tool invocation, and inter-agent interaction recorded and queryable.
Guardrails and policy enforcement
Configurable input/output filtering and safety controls applied consistently across all models and access paths - global or scoped per team and use case.
AI inventory and model registry
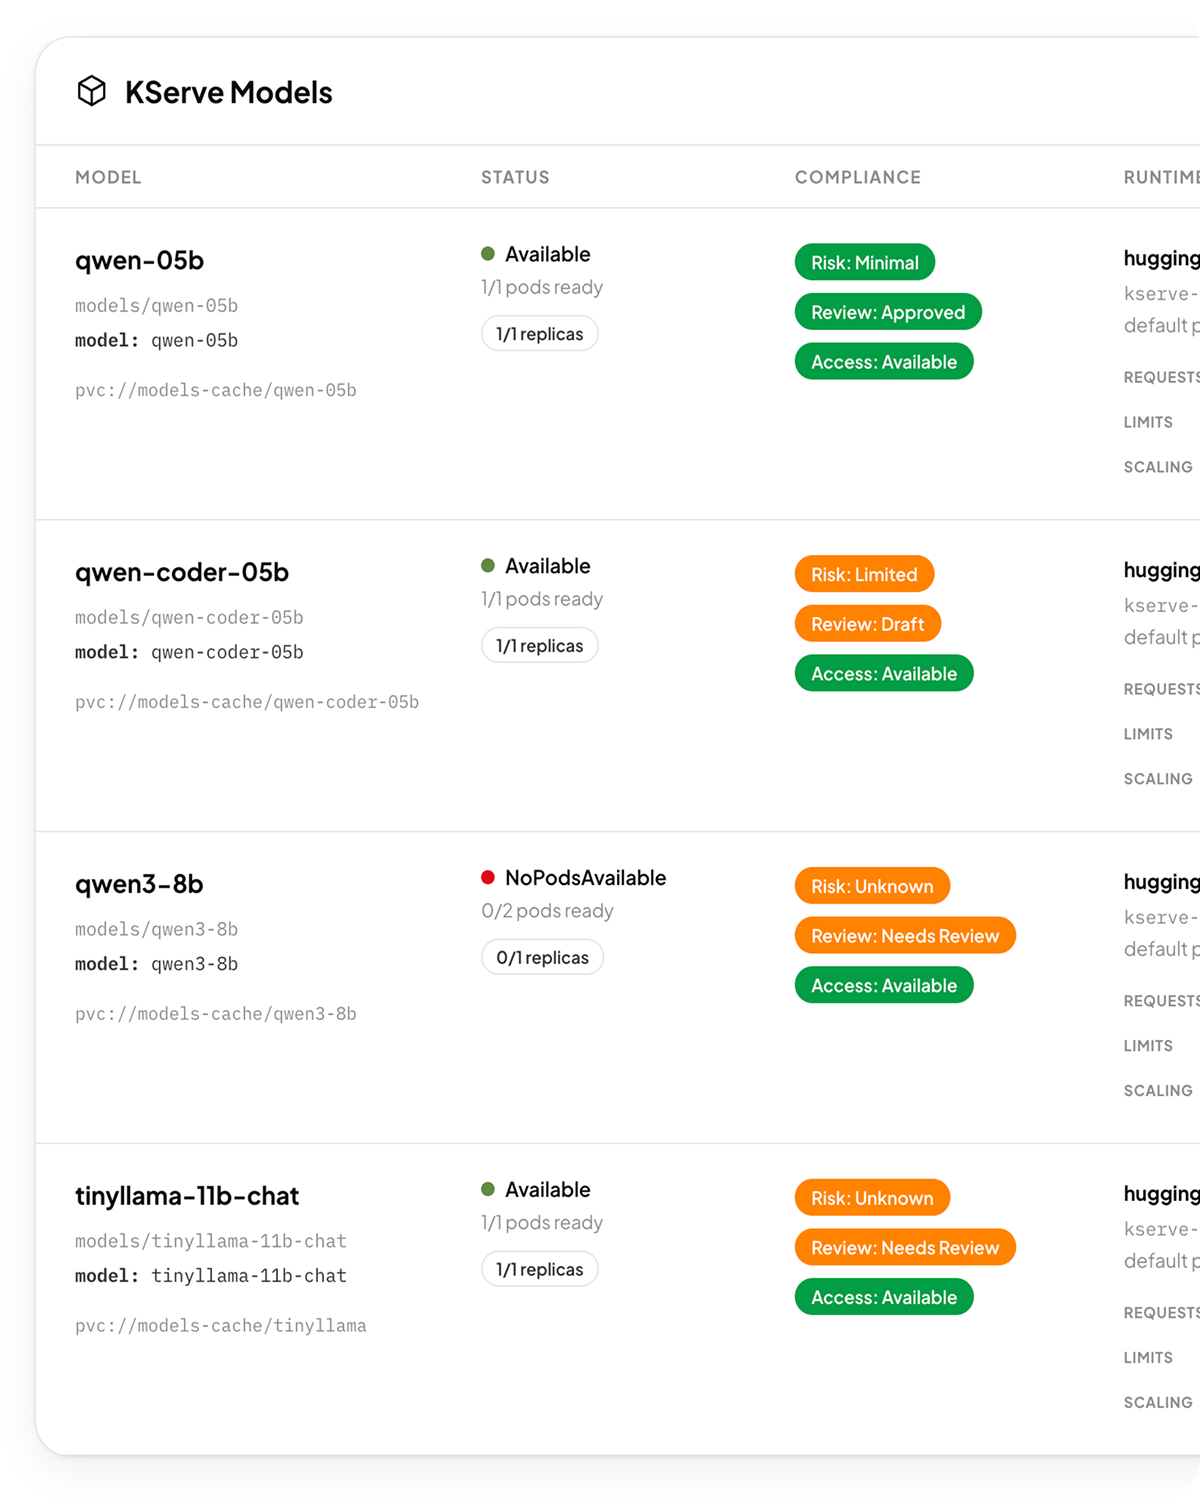
A complete AI inventory of every model, agent, and application deployed across the organization. With risk classifications, intended use, and access records - foundational for EU AI Act compliance.
Ready to take control of AI in your organization?
Book Aiboostr demo
See what governed AI actually looks like
Field notes for the people who actually run AI on how to bring every model and agent under control, meet the EU AI Act, and keep sensitive data in-house.
Compliance as a runtime property, not a document trail
Which model produced this output, what went into the prompt, and who could see the result? Answering questions like this usually starts a small archaeology project: exporting logs, finding the engineer who remembers the deployment, reconciling what turns up against a register that was accurate on the day it was written. The answer normally arrives, assembled by hand. Producing it again next quarter means repeating the exercise.
The EU AI Act turns that question into a standing obligation, and the date for the largest part of it just moved. The omnibus agreement reached by the EU institutions in May 2026 pushes high-risk obligations to 2 December 2027 for stand-alone systems under Annex III and 2 August 2028 for AI embedded in regulated products under Annex I. Nothing else moved: the general-purpose AI rules have applied since August 2025, the Article 50 transparency duties arrived on 2 August 2026, and the Article 5 prohibitions are in force.
The interesting question is what that time is for. It can go into getting better at the archaeology running the exercise faster, with more people who know where to look. Or it can go into building systems that answer those questions on their own.
What EU AI Act compliance actually asks for
Read Article 12 closely and the requirement is technical. High-risk systems must allow for the automatic recording of events over the lifetime of the system, at a level of traceability appropriate to the system's purpose, sufficient to identify situations where the system may present a risk or undergo substantial modification, and to support post-market monitoring.
Article 19 adds retention: providers keep the logs their systems automatically generate for a period appropriate to the intended purpose, and in any case at least six months.
The word doing the work in both places is automatic. Both articles describe a property the system has to possess while running. Documentation about how logging ought to work leaves the requirement unmet.
The same is true across most of the obligations. What data entered the model. Which version was serving in April. Who had access, and when. Whether human oversight actually engaged, or merely existed on an org chart. Every one of these is a question about the behavior of a running system, answerable only from a record that the system produced while running.
Why a GRC platform cannot be the source of truth
GRC platforms are good at what they were built for: policies, attestations, control libraries, risk registers, questionnaires. That is the intent layer, and it matters the AI Act does require documented governance, and an organization without it is starting from behind.
But intent and behavior are different layers, and only one of them is evidence. When the controls live in a system beside the one being governed, the evidence has to be assembled by hand: someone exports logs, someone reconciles a spreadsheet against a deployment, someone asks an engineering team what changed six months ago. Two things follow, and both are avoidable.
The first is drift. A declared control and an operating system diverge quietly, and the gap is discovered at audit rather than at the moment it opened.
The second is cost. If evidence is produced by people, every audit, every customer security review and every regulatory inquiry is a project with a budget.
The scale of the gap is visible in the data. In Vision Compliance's 2026 EU AI Act Readiness Report, published in April 2026 across eight industries, 61% of organizations had no process for generating the required technical documentation data governance records, model performance metrics, human oversight procedures. 74% had no designated internal owner for AI compliance, and 83% had no formal inventory of the AI systems they use or deploy. The report's own summary of the problem is worth quoting: most organizations know the AI Act exists, but few appreciate that "the regulation goes well beyond policy statements."
That last figure is the one that compounds. An AI system inventory assembled manually for an audit is a snapshot of what someone could remember and find; the obligations it feeds are continuous.
Controls that run where the AI runs
The alternative is to put the control at the point of execution, which in practice means the layer every model call already passes through.
An AI gateway sitting between applications and models is in a position to do what a parallel governance system cannot. It records the model and version that served each call, the application and team that made it, and the access path used not because anyone declared it, but because that is what passing through looks like. Input and output filtering applies there, consistently, rather than being reimplemented in each application with its own interpretation of the policy. Risk classification lives with the system in a registry that updates as the system changes.
The important shift is what a policy becomes. In the document-trail model, a policy is a statement about a system, and compliance is the ongoing work of keeping the statement true. In the runtime model, the policy is the configuration the system runs on. The two cannot drift apart, because they are the same object. Evidence stops being something you produce and becomes something you already have.
This is the distinction worth applying when evaluating an AI governance platform: does it describe the estate, or does it sit in the path of it? A tool that ingests declarations is a better filing cabinet. A tool in the request path is a control.
GRC as the consumer of the record, not its collector
None of this argues for replacing a GRC programme. Risk appetite, accountability, sign-off, third-party assessment those belong exactly where they are, and the AI Act expects them.
What changes is the direction of the data. Instead of the GRC function chasing engineering teams for evidence each quarter, the runtime emits a continuous record and GRC consumes it: current inventory, current risk classification, access history, retained logs with a retention policy that satisfies Article 19 without anyone remembering to set it.
EU AI Act compliance software is genuinely useful in that arrangement, because it finally has something reliable to work with. The same tool sitting on top of manually gathered inputs inherits every weakness of the gathering. Which suggests a different reading of the 61% figure above: what most organizations are missing is a source of technical evidence for a compliance platform to draw on.
What the extra fifteen months are for
The systems being deployed now are the systems that will be in scope in December 2027. Retrofitting traceability into a production system is materially harder than having it from the start and unlike a documentation exercise, it cannot be completed in the quarter before a deadline.
There is also a practical argument that has nothing to do with the regulator. Prompt- and response-level records, model version history and access logs are what you need when a customer asks how the system arrived at what it told them, when an internal review needs to reconstruct an incident, or when a model upgrade changes behavior in a way nobody expected. Organizations that build this only for the AI Act tend to find they were the primary users of it all along.
Aiboostr was built on that premise. Guardrails, tracing, the model and agent registry and risk classification are enforced and recorded at the point of execution, so the compliance record is a by-product of running the estate rather than a separate exercise performed on top of it. Whether an auditor ever asks is, in a sense, beside the point: the same record is what makes the system operable.
Compliance in this shape stops being a project with an end date. It becomes a property of the environment and properties do not need to be renewed.
Sources
- Regulation (EU) 2024/1689 (AI Act), Article 12 (record-keeping) and Article 19 (automatically generated logs)
- EU institutions' omnibus agreement on AI Act timelines, May 2026 Annex III high-risk obligations deferred to 2 December 2027, Annex I to 2 August 2028, binding once published in the Official Journal; GPAI, Article 50 transparency and Article 5 prohibitions unchanged
- Vision Compliance, "2026 EU AI Act Readiness Report", April 2026 assessment across eight industries
Stop benchmarking your private model against the wrong opponent
A team stands up an open-weight model on internal infrastructure, points it at the same broad set of questions they used to try out a commercial model six months earlier, reads both sets of answers side by side, and concludes that private models are not there yet.
The comparison was run carefully. The conclusion follows from it. And it answers a question nobody in the organization had asked, because nobody proposed replacing a frontier model at everything.
How far behind open-weight models actually are
The general capability gap is real, and it is smaller than the pilot above suggests. Epoch AI tracks it with the Epoch Capabilities Index, a composite measure of model capability, and reported in May 2026 that since January the most capable open-weight models have trailed frontier closed models by an average of four months, or roughly 8 ECI points -a distance Epoch compares to the step between two consecutive versions of the same commercial model family.
Worth stating the caveat: ECI is Epoch's own composite index, and any single number that summarises "capability" carries assumptions about which capabilities count. That caveat happens to be the point of this article.
Still, four months is a useful figure for a planning conversation, because it reframes the choice. A four-month lag on a fast-moving frontier is not a technology generation. It means a self-hosted stack that can adopt new open weights as they land operates a short distance behind the leading edge, permanently -and the distance is measured in the same units as your own release cadence.
Why a general benchmark is the wrong instrument for a specific job
A composite index averages performance across mathematics, code, long-context reasoning, multilingual work, agentic tool use and much else. An enterprise use case draws on a thin slice of that surface. Classifying incoming tickets into eleven categories, extracting nine fields from a supplier invoice, answering questions from a fixed corpus of internal documentation, summarising a shift report into a defined template -none of these require the breadth that separates the top of the leaderboard from the model four months behind it.
On a narrow task, most of the quality comes from the system around the model. Retrieval that surfaces the right passage. A prompt shaped to the task rather than to a demo. Structured output the downstream system can rely on. Validation that catches malformed answers before a user sees them. A few hundred labelled examples for a light fine-tune. Change any of those and the measured difference between two models moves more than the models themselves differ.
This is the argument NVIDIA's research group made in their 2025 position paper on small language models in agentic systems: where specialized tasks repeat with little variation, smaller models are sufficient for the work and considerably more economical to run. The interesting consequence for anyone evaluating a private AI platform is that the leaderboard gap and the gap on your task are two different quantities, and only one of them appears in any published comparison.
How to design a comparison that answers your question
Four rules turn a model bake-off from an impression into a decision.
- Build an evaluation set from your own traffic. One or two hundred real cases with the expected result beats any public benchmark, because it measures the task you actually run rather than an average across tasks you do not. Production requests are also messier, shorter and more repetitive than the examples a project team invents in a workshop - and that difference usually favours the smaller model.
- Fix the acceptance criterion before the test. "Better" decides nothing. "No more than three points of accuracy lost for a sixty per cent lower cost per call, with no regression on the twelve cases the legal team flagged" decides something. Without a threshold agreed in advance, the discussion ends in impressions and the incumbent wins by default.
- Compare complete paths, not bare models. A private model with good retrieval measured against a frontier model with none is an equally uninformative test in the opposite direction. Put both in the configuration you would actually ship.
- Measure on live traffic, in the shape it arrives. A slice of production, mirrored to both candidates, produces evidence. A curated demo set produces agreement in the room and surprises later.
Where the platform layer does the work
Each of those rules is cheap or expensive depending on where your models are consumed. If every call already passes through one place, most of the cost disappears.
Prompt- and response-level tracing gives you the evaluation set for free: the cases are the ones your users actually sent, captured as they happened, rather than reconstructed from memory. An AI gateway lets you route the same traffic to two models and collect comparable results, without touching the applications making the calls. Cost and usage monitoring supplies the other half of the equation, since the decision is a ratio and half of it is money. And private model serving with versioning and gradual rollout means the winner can go live on a slice of traffic first, with a way back if the evaluation missed something.
This is also where the sovereignty argument stops being abstract. A sovereign AI platform that runs the model inside your own perimeter is only useful in practice if switching to it is a measurable, reversible decision rather than a leap of faith. The evaluation machinery is what makes it the former.
The question has a shelf life of about a quarter
"Is an open-weight model good enough" has no general answer and never will. It has an answer per use case, and that answer expires -new open weights land every few weeks, the four-month gap moves, and a task that failed the test in March may pass it comfortably in September.
Which makes the durable capability the ability to run the test cheaply. An organization that needs six weeks and a project sponsor to compare two models will do it once, cite the result for two years, and be wrong for most of that time. An organization that can mirror traffic to a candidate model and read the numbers a day later will do it whenever something new shows up, and spend the difference on the use cases that are working.
Aiboostr exists to make that second pattern the default: one place where models are registered and consumed, real traffic available as evidence, cost attached to each option, and a controlled path to production for whichever one wins. The AI orchestration platform is what turns "good enough" from an opinion into a measurement you can repeat.
Sources
- Epoch AI, "Open models lag state-of-the-art closed models by 4 months", data insight published 29 May 2026 -Epoch Capabilities Index, average gap of ~8 ECI points since January 2026
- P. Belcak, G. Heinrich et al., "Small Language Models are the Future of Agentic AI", NVIDIA Research, 2025 -position paper on the sufficiency and economics of small models for specialized, repetitive agentic subtasks
The cost of an agent is not the cost of a prompt
A user clicks a button. Behind it, an agent reads a 200-page contract into context, calls four internal tools, retries two of them, spawns a sub-agent to check a supplier record, and returns an answer. The next click, from the same user in the same interface, costs a fraction of a cent.
Nothing about that is a defect. It is how agentic systems work. But it breaks an assumption that sits underneath most corporate budgeting: that consumption scales with activity. Seats, requests, logins, transactions - for thirty years, IT spend has been forecast by counting something a user does. Agentic AI is the first category where the same user action can differ in cost by three orders of magnitude, and where nobody can tell in advance which one they are about to get.
Why AI agent costs don't scale with your users
The multipliers are large and well documented. Anthropic's own engineering data puts it plainly: "agents typically use about 4× more tokens than chat interactions, and multi-agent systems use about 15× more tokens than chats."
The academic picture is starker still. A May 2026 study from the Stanford Digital Economy Lab and Microsoft Research, analysing token consumption in agentic coding tasks, found that agentic execution consumed up to 1000× more tokens than code chat on comparable work. More usefully for anyone trying to build a forecast, it found that running the same agent on the same task produced token bills that varied by as much as 30×.
That last number is the one worth sitting with. It means the variance is not primarily explained by which team is using the system, or how many people are using it, or how hard the task looks. It is intrinsic to the execution.
The study also identified where the money went in the systems it measured, and it is not where most people assume: most of the cost came from input tokens rather than output, because the agent re-read the original instruction and the record of its own previous steps before choosing each new action.
How strongly that holds anywhere else is a design question - how much history an agent carries forward is engineering, not physics. Which is rather the point: two organizations running comparable use cases can end up with entirely different cost profiles, and neither can infer its own from a published benchmark or a vendor's pricing page.
There is a governance implication hiding in a related finding: the models themselves consistently underestimate how many tokens they will spend. Self-reported estimates are not a control.
Why stopping runaway agent costs belongs in the LLM gateway
In traditional systems, a bad loop degrades response times and someone opens a ticket. In an agentic system, a bad loop bills. The failure is silent, fast, and financial - and the first signal is often the invoice.
In Harness's 2026 State of AI in FinOps report, based on a survey of 700 engineering leaders and practitioners across five countries, 72% said they had experienced unexpected AI cost spikes in the past year, and a third were caught out more than once. When a spike happened, only 20% could identify what caused it within hours.
Read those two figures together and the shape of the problem is clear. The issue is not that organizations lack budgets - 73% report having cost policies in place. It is that the budget operates on a monthly cycle while the risk operates on a per-execution one, and the diagnostic tooling operates on neither.
The control that matters here is not a bigger budget or a stricter approval process. It is a circuit breaker: a hard ceiling on what a single run may consume, enforced at the point of execution. An LLM gateway that every call passes through is the only place that limit can be applied consistently, because it is the only component that sees every call regardless of which application, team or framework made it. A per-run cap, a per-agent rate limit and a per-team budget are three different controls, and an agentic estate needs all three.
AI cost attribution tells you who. Tracing tells you why.
Most conversations about AI cost stop at attribution - splitting the vendor invoice across teams and projects. That is a necessary first step, and it is missing more often than not: the same Harness survey found that 52% of organizations have no clear owner for AI costs, and that while 73% have cost policies, only 13% have basic spending visibility. Fewer than 45% of engineers say they understand the cost of the features they build.
But attribution on its own does not change anything. "Team X spent 40,000 this quarter" is a fact, not a decision. It tells a finance lead where to direct a difficult conversation, and it tells the engineering lead on the other side of that conversation nothing they can act on.
What makes the number actionable is the layer below it: a trace of what happened inside a single run. How many steps did the agent take? How many were retries? How large was the context on step one versus step nine? Which tool call returned a payload that then rode along in every subsequent prompt?
Those questions have concrete answers, and the answers point at concrete fixes - caching a stable prefix, trimming what gets carried forward between steps, routing a mechanical sub-task to a smaller model, capping retry depth. This is the difference between cost reporting and cost engineering, and it is why AI agent governance cannot be built from billing data alone. Invoices are aggregated by vendor and model. The cost structure that explains them exists only in the execution record.
What to look for in an AI orchestration platform
If cost control is a requirement rather than a report, a few capabilities separate the options:
- Limits enforced per run, not just per month - a monthly budget cannot stop an incident that completes in ninety minutes
- Cost attached to a use case, not a vendor - the unit a business decision is made about is the use case, and it usually spans several models
- Trace-level breakdown - steps, retries and context growth within a single execution, not just totals
- One view across providers and self-hosted models - otherwise every comparison is manual and every gap is a blind spot
- Coverage of agent-to-agent calls - in a multi-agent orchestration platform, a chain that looks like one request from the outside may be a dozen model calls with distributed ownership
Aiboostr applies these at the layer where they can actually be enforced. The AI gateway carries token budgets and rate limits as policy rather than as application code, including caps scoped to a single agent session rather than a billing period - so a loop stops at a ceiling instead of at the end of the month. Usage and cost are attributed down to the use case, and prompt- and response-level tracing exposes the structure of a run, so the question after a spike is which step grew and why, not which vendor to email.
There is a broader point about enterprise AI orchestration in this. Cost, once it is measured at execution level, turns out to be one of the better health signals available: a sudden change in cost per run usually indicates that something changed in behavior - a longer context, a new tool, a retry loop, a model swap - and it frequently surfaces before any user files a complaint.
The realistic goal: bound AI agent costs, don't forecast them
AI spend cannot be forecast the way seat-based software is forecast. The variance is real, it is intrinsic to how agents work, and no amount of planning discipline will remove it - the research is unambiguous on that point.
What can be done is to bound it. A ceiling on the individual run, a budget per use case, an alert on the outlier, and a trace that explains the number after the fact. That is an achievable target, and it is a more honest one to put in front of a CFO than a forecast that assumes agents behave like software licences.
Sources
- Anthropic, "How we built our multi-agent research system" - token multipliers for agents and multi-agent systems
- L. Bai, E. Brynjolfsson, A. Pentland, J. Pei et al., "How Do AI Agents Spend Your Money? Analyzing and Predicting Token Consumption in Agentic Coding Tasks", Stanford Digital Economy Lab / Microsoft Research, May 2026
- Harness, "2026 State of AI in FinOps", survey of 700 engineering leaders and practitioners across five countries, May–June 2026
FAQ
AI governance questions, answered.
An AI governance platform gives an organization one place to control how every AI model and agent is deployed, accessed, and monitored. It combines an AI inventory, access controls, guardrails, cost tracking, and compliance evidence — so AI scales across teams without losing visibility, security, or regulatory oversight.
Aiboostr builds EU AI Act compliance into your infrastructure. It maintains a governed AI system inventory, enforces policies, retains interaction logs, and monitors AI continuously — producing audit-ready evidence from day one. Compliance is embedded in the platform, not bolted on after deployment.
An AI gateway is a single, governed access point for every AI model — private and public. It enforces access policies, rate limits, and token budgets per team, provides one unified API across providers, and records a full audit trail on every call for cost control and compliance.
Governing agentic AI means controlling not just the model but every action an agent takes. Aiboostr runs agents in a stateful, governed runtime, connects them to enterprise systems through MCP-based tool integration, and traces every LLM call and tool invocation — so autonomous behavior stays visible and enforceable.
Aiboostr deploys on your existing infrastructure — any Kubernetes environment, on-premises, on EU cloud providers, or any major public cloud, with no migration required. Regulated organizations keep AI, data, and governance inside their own perimeter and data-residency boundary.
Shadow AI is any AI model, agent, or tool used inside an organization without approval or oversight. Aiboostr surfaces it by routing all model traffic through a single AI gateway, so every call is logged and unsanctioned usage becomes visible — then brought under one governance policy.
Yes. Aiboostr runs open-source LLMs directly on your own infrastructure, so sensitive data never leaves your environment. You get full AI capability with zero data exposure to external APIs — with private model serving, autoscaling, versioning, and staged deployments included.
An AI inventory is a complete registry of every AI model, agent, and application deployed across an organization, with risk classifications, intended use, and access records. It is foundational for EU AI Act compliance, which requires organizations to document and monitor the AI systems they operate.
Aiboostr provides a self-service catalog where business units discover, request, and access approved AI models and agents on their own — without manual provisioning by platform teams. Governance stays centralized while delivery stays self-service, so teams move fast and IT keeps control of access, cost, and policy.
An AI gateway controls traffic — it routes and enforces policy on every model call. An AI governance platform documents and manages risk across the AI lifecycle: inventory, compliance, and monitoring. Aiboostr combines both, so the gateway's audit trail feeds governance automatically.